
↔
Reuse your data foundation
Access measurements and metadata from existing ODS environments rather than creating another parallel engineering repository.
PEAK ODS ADAPTER FOR APACHE SPARK
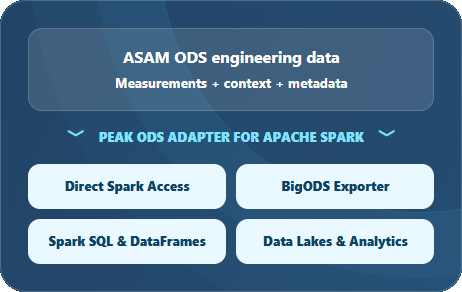
Open standards · Spark SQL & DataFrames · Parquet / Avro / JSON · Scale as needed
FROM ENGINEERING DATA TO ANALYTICS VALUE
Test data is often rich in technical meaning but difficult to use outside its original engineering environment. The Peak ODS Adapter for Apache Spark connects domain-specific ASAM ODS data management with familiar scalable data technologies.
Access measurements and metadata from existing ODS environments rather than creating another parallel engineering repository.
Use Spark SQL and DataFrames to select and process the engineering information needed for each analysis.
Grow from local analytics to distributed processing with appropriately configured Spark resources and licenses.
Export defined data selections in standards-oriented formats that fit existing lake and analytics workflows.
ONE ENGINEERING DATA FOUNDATION · TWO INTERGRATION PATHS
Choose the integration pattern that fits your workload. Both paths start with the same well-described ASAM ODS measurement data.
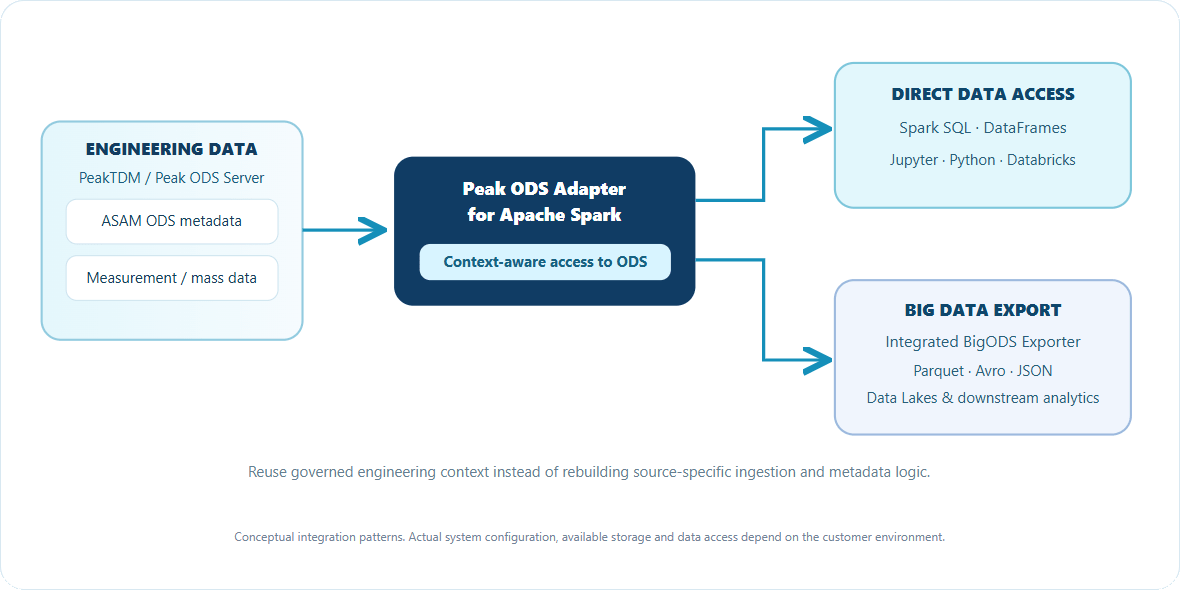
Query ODS instance data and measurement values with Spark SQL and DataFrames. Work with selected signals in Python, Jupyter or other Spark-based applications, using scalable resources when needed.
Prepare selected engineering data as files optimized for the target big-data environment. The BigODS Exporter is part of the Peak ODS Adapter for Apache Spark — not a separate standalone platform.
INCLUDED COMPONENT · PEAK BIS ODS EXPORTER
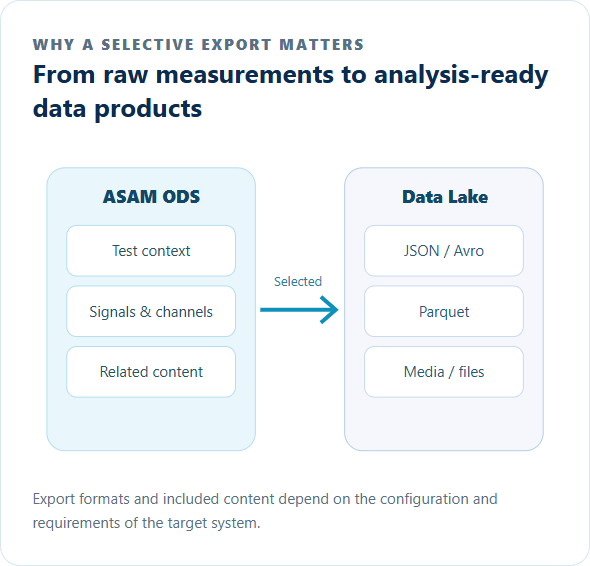
Enterprise analytics does not always require copying complete test campaigns. The integrated BigODS Exporter lets teams define what to export, preserve technical context, and supply analytics environments with structured datasets.
Use XML-based Export Definition Files to describe the ODS data subset required for a specific workload.
Include engineering metadata and relationships alongside measurement values, with optional additional files such as media or documents.
Export metadata and instance data as JSON or Avro, and measurement mass data as Parquet for downstream processing.
WHERE TEAMS PUT IT TO WORK
Analyze selected time-series channels and engineering metadata from existing ASAM ODS repositories using SQL, Python and notebooks.
Connect a trusted engineering data foundation to Spark-based enterprise analytics, without duplicating core TDM functionality.
Export purpose-defined ODS datasets to open big-data formats for broader data engineering and analytical use.
APPLICATION EXAMPLE · GLOBAL AUTOMOTIVE MANUFACTURER
In a global automotive implementation, Peak Test Data Manager provides an ASAM ODS-based, multi-domain engineering data foundation. The Peak ODS Adapter for Apache Spark connects this foundation to Databricks for scalable enterprise processing and analytics.
Scalable enterprise analytics, Spark-based processing and AI development capabilities.
Reusable access to ASAM ODS metadata and measurement data through Spark SQL and DataFrames.
Domain-specific metadata models, test data ingestion, validation and controlled access across engineering disciplines.
Instead of reconstructing ingestion, metadata management and engineering-tool integration for every new analytics initiative, the customer relies on a reusable data foundation with a dedicated integration layer.
The integration is an implemented customer architecture. Examples such as anomaly detection, predictive engineering and AI assistants are possible future applications, not claimed delivered project results.
ANSWERS BEFORE YOU GET STARTED
No. Direct Spark access can work with the existing ODS data infrastructure. For Data Lake use cases, the BigODS Exporter can export selected datasets, avoiding indiscriminate duplication. The exact deployment depends on storage access and the customer architecture.
Yes. Peak BigODS Exporter is a functional part of the Peak ODS Adapter for Apache Spark and implements the ASAM ODS Big Data Connector export approach.
Yes. PeakTDM has been integrated with Databricks in a global automotive customer architecture via the Peak ODS Adapter for Apache Spark. The specific Spark, network, authentication and deployment setup is project dependent.
No. The adapter operates on ASAM ODS data. Its applicability depends on the available ODS data model and the requirements of your testing or simulation domain.
Yes. The solution can be used with local Spark resources and scaled to more powerful clusters as needs grow, subject to licensing and infrastructure requirements.
Tell us about your current data infrastructure and analytics goals. We will explore the most suitable integration route — direct Spark access, configurable data-lake exports, or a combination of both.
One data foundation. Connected engineering workflows.
Discover the components and technologies that help you build a complete, standards-based test data environment.
Peak Test Data Manager
Discover the full engineering data management platform behind the Workplace.
Peak ODS Server
Store and access measurement data through open ASAM ODS models and standardized APIs.
Peak Data Transfer Tool
Automate import, cleansing and metadata enrichment from different test systems and file formats.
Peak Permission Manager
Control access to sensitive technical data using managed permissions at various levels.
Explore More on This Topic
Discover related articles, practical insights, and additional solutions to explore this topic in greater depth. Learn more about relevant technologies, real-world applications, and how they can benefit your business.
Peak Test Data Manager Meets Databricks
See how a global automotive manufacturer connects trusted engineering data with enterprise-scale analytics and AI.
Bridge the gap between ASAM ODS and Big Data Lakes:
Learn how to bring your contextualized ASAM ODS data into Big Data Lakes - without rebuilding your existing data infrastructure.
Unlock deeper insights from test data with Apache Spark
Discover how scalable data processing and direct access to ASAM ODS measurement data enable faster analysis, advanced analytics, and AI.
